Python SDK25.5a Burn Lag: Causes, Diagnosis and Fixes
November 9, 2026
0
An application can work perfectly during initial testing and still become noticeably slower after running for several minutes. A request that normally completes almost instantly may begin taking
An application can work perfectly during initial testing and still become noticeably slower after running for several minutes. A request that normally completes almost instantly may begin taking several seconds. CPU usage can rise unexpectedly, memory consumption may continue increasing, and background operations might stop responding at the speed users expect. When this happens in a Python-based project, developers naturally begin investigating the interpreter, installed packages, external services, and software development kits involved in the application.
One search phrase that raises questions in this area is python sdk25.5a burn lag. It appears to combine a Python SDK identifier with a performance symptom, but the terminology requires careful interpretation. There is not enough established information to identify Python SDK25.5a as an official Python release or to confirm that burn lag is a documented defect associated with it. It would therefore be inaccurate to describe the phrase as the name of a verified Python bug.
A more useful approach is to investigate what the phrase might represent. It could refer to a particular third-party SDK version, a development environment, an application-specific component, or a reported slowdown that someone has associated with a version label. Regardless of the exact identity, developers can investigate the symptoms using established performance engineering techniques. Measuring execution time, examining CPU and memory behavior, checking network activity, and comparing dependency versions can reveal where an application is losing time.
This guide explains how Python SDKs interact with applications, why performance can deteriorate, and how developers can systematically investigate suspected SDK-related lag without assuming that an unverified version is responsible.
Python SDK25.5a Burn Lag: Technical Overview
Fact
Details
Topic
Python SDK25.5a Burn Lag
Technology
Python
Technical Area
Software Performance
Main Concern
Possible execution slowdown
Related Resources
CPU, memory, storage and network
Potential Symptoms
Delays, freezing and slow execution
Diagnostic Approach
Profiling and debugging
Relevant Tools
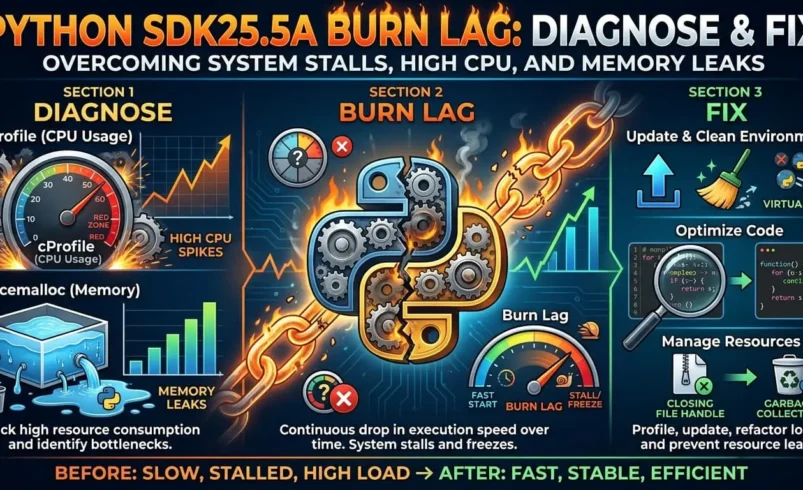
cProfile, tracemalloc and logging
SDK Identity
Requires independent verification
Problem Status
Not established as an official Python error
What Does Python SDK25.5a Burn Lag Actually Describe?
The phrase Python SDK25.5a burn lag should first be treated as a search term rather than a confirmed technical diagnosis. In software development, an SDK, or software development kit, is generally a collection of tools, libraries, documentation, and interfaces that help developers build applications for a particular platform or service. An SDK may include Python packages, authentication helpers, API clients, configuration utilities, and examples.
The label 25.5a could potentially be a vendor-specific version identifier, a package build label, an internal release name, or a reference used in a particular development environment. Its format alone does not establish that it belongs to the official Python language release cycle. Developers should identify the publisher, package name, distribution source, and version metadata before associating it with a specific product.
The word burn is equally important to interpret carefully. It might be used informally to describe excessive resource consumption, sustained CPU activity, overheating hardware, or a process that becomes increasingly demanding. Lag usually describes a noticeable delay between an operation being requested and the application completing it. These terms can describe related symptoms, but they do not identify a single technical cause.
For example, an application may experience lag because a function performs unnecessary calculations. Another may become slow because it waits for a remote server. A third may consume increasing memory because objects remain referenced after they are no longer needed. All three situations can look similar to a user, even though their technical causes are completely different.
The first step is therefore to translate the phrase into measurable questions: Which operation is slow? When does the delay begin? Does CPU usage increase? Is memory consumption growing? Are network requests taking longer? Does the problem occur only after installing a particular package version? These questions provide a practical starting point for troubleshooting Python SDK performance issues.
How Python SDKs Influence Application Performance
A Python SDK normally sits between application code and an external service, platform, or system component. Instead of manually constructing every request, handling authentication, interpreting responses, and managing connection details, developers can use the SDK’s functions to perform those tasks through a more convenient interface.
This convenience does not mean that an SDK operates independently of the application. Its functions still execute within the application’s runtime environment and use system resources. Depending on its design, an SDK may perform data conversion, validation, serialization, network communication, retries, caching, or background processing. Each activity can affect execution time.
Consider an application that sends information to an external API. The application might call a method provided by an SDK, which then validates the supplied values, prepares a request, sends it over the network, receives a response, and converts that response into Python objects. If the operation takes three seconds, the delay could come from the remote server, the network connection, local processing, or a combination of these factors.
It would be misleading to blame the SDK simply because the application uses it. A useful investigation separates time spent inside the application from time spent waiting for external systems. This distinction becomes especially important when an application depends on several packages and services.
A software product’s purpose also matters when evaluating its behavior. For example, a document-focused application such as AxelaNote has a different workload from a Python API client. One may spend much of its time handling document annotations, while another may wait for network responses or process structured data. Performance should always be assessed in relation to the actual work an application performs.
Why Python Applications Become Slower During Execution
Performance problems rarely have one universal explanation. A Python application may slow down because of inefficient code, repeated data processing, excessive memory allocation, blocked network calls, slow disk operations, or an unsuitable dependency configuration. Several of these conditions can also occur together.
The timing of the slowdown provides an important clue. If an application is slow from its first operation, the cause may involve startup overhead, configuration, imports, or an expensive initialization routine. If performance gradually deteriorates, developers should investigate memory growth, accumulating tasks, repeated database queries, connection handling, and background processes.
A sudden slowdown after a deployment suggests a different investigation. Developers should compare the new environment with the previous working configuration, including Python versions, package versions, operating system changes, environment variables, and external service behavior.
CPU-Intensive Operations and Processing Bottlenecks
CPU usage rises when a process performs calculations or other work that requires processor time. Some workloads naturally need substantial processing, such as image manipulation, data transformations, mathematical simulations, large sorting operations, and complex parsing.
The problem appears when an application performs more work than necessary or executes expensive operations too frequently. A function that repeatedly scans a large collection, for example, may take increasingly long as the collection grows. Nested loops can also create significant processing costs when they operate over large datasets.
A useful first step is to measure the duration of the operation rather than relying on how busy the computer appears.
import time

def process_records(records):
    result = []

    for record in records:
        result.append(record.strip().upper())

    return result

records = ["sample record"] * 100000

start = time.perf_counter()
processed = process_records(records)
elapsed = time.perf_counter() - start

print(f"Execution time: {elapsed:.4f} seconds")
This example measures the time required to process a collection of strings. The time.perf_counter() function is suitable for measuring short elapsed intervals because it provides a high-resolution performance counter.
However, one measurement does not establish a reliable benchmark. Results can vary because of background processes, CPU frequency changes, system load, and other environmental factors. Developers should repeat measurements under consistent conditions and use representative data.
Memory Consumption and Gradual Slowdowns
Python manages memory automatically, but automatic memory management does not mean applications cannot use excessive memory. A program may keep references to objects that are no longer required. Large lists, dictionaries, cached responses, retained log records, and unfinished tasks can all contribute to increasing memory consumption.
A memory leak is generally suspected when memory usage continues growing without a corresponding need and does not return to an expected level after work has completed. However, a rising memory graph alone is not proof of a leak. Some applications intentionally retain objects for caching or reuse.
Python’s tracemalloc module can help developers inspect memory allocations made by Python code.
import tracemalloc

tracemalloc.start()

records = []

for number in range(100000):
    records.append({"id": number, "status": "active"})

snapshot = tracemalloc.take_snapshot()

for statistic in snapshot.statistics("lineno")[:10]:
    print(statistic)

tracemalloc.stop()
This example records memory allocation information and displays the source locations associated with the largest traced allocations. It can help identify code that creates many objects.
There are limitations. tracemalloc focuses on Python memory allocations and does not represent every allocation made by native extensions or the entire operating system process. Developers investigating total process memory may also need operating-system monitoring tools. Comparing snapshots before and after a workload can provide more useful information than looking at one snapshot in isolation.
Network Requests and Input/Output Delays
Not every slow Python operation is caused by slow Python code. Applications that communicate with external services often spend a significant amount of time waiting for network responses.
An SDK may send a request to a remote API and wait until the service responds. If the service is overloaded, the network connection is unstable, or the request requires substantial server-side processing, the application may appear frozen even when the local CPU is mostly idle.
Storage operations create similar problems. Reading large files, writing frequent logs, accessing remote storage, and querying databases can introduce delays that are not visible through CPU measurements alone.
Developers should measure individual stages of a request. For example, they can record when a request begins, when the response arrives, and how long response processing takes. This separates network waiting from local computation.
Timeouts are also important. A request without an appropriate timeout may wait much longer than the application can reasonably tolerate. Retries can make matters worse if each failed attempt creates another delay. A well-designed integration should use sensible timeouts and controlled retry behavior.
How to Identify Whether an SDK Is Responsible
An SDK can contribute to slow execution, but developers need evidence before assigning responsibility. A useful investigation begins by identifying the exact package and version involved.
The term Python SDK25.5a is not enough to establish package identity. Developers should check the project’s dependency file, installed distribution metadata, installation command, and documentation provided by the package publisher.
For an installed package, Python’s package metadata tools can reveal its version:
from importlib.metadata import version, PackageNotFoundError

package_name = "requests"

try:
    print(f"Installed version: {version(package_name)}")
except PackageNotFoundError:
    print(f"{package_name} is not installed")
Replace requests with the actual distribution name being investigated. The distribution name and the name used in a Python import statement are not always identical, so developers should verify the correct package identifier.
The command-line alternative is:
python -m pip show requests
This displays information about the installed package, including its version and installation location. Running the command through the same Python environment used by the application is important. A system can contain multiple Python installations or virtual environments, and checking the wrong one can produce misleading results.
Compare a Working Environment With the Problem Environment
If an application worked before a dependency change, compare the previous and current configurations. Look for updates to the SDK, its dependencies, the Python interpreter, and other packages installed at the same time.
A controlled comparison is more useful than changing several dependencies together. If multiple packages are upgraded or downgraded simultaneously, it becomes difficult to determine which change influenced performance.
A developer can create a separate virtual environment, install the previous known-good dependency set, and run the same test workload. The comparison should use identical input data, configuration, and external service conditions wherever possible.
If the slowdown appears only in one dependency configuration and can be reproduced consistently, the evidence for a version-related issue becomes stronger. It still does not prove the SDK itself is defective, but it narrows the investigation.
Using cProfile to Find Slow Functions
Python includes cProfile, a deterministic profiler that records information about function calls and execution time. It can help identify which parts of a program consume the most time during a particular workload.
A simple example is:
import cProfile

def calculate_total():
    total = 0

    for number in range(1_000_000):
        total += number * number

    return total

cProfile.run("calculate_total()")
The profiler reports information such as the number of calls and time spent in functions. This can help identify expensive operations that deserve closer inspection.
For a larger application, profiling can be run from the command line:
python -m cProfile -s cumulative app.py
The cumulative sorting option helps show functions that account for substantial time, including time spent in functions they call. Developers can use the output to identify expensive parts of an application before attempting optimization.
Profiling also has limitations. It introduces some overhead, so measured execution time may differ from normal execution. A profile describes the workload that was actually executed; it cannot reveal the performance of code paths that were never reached. For this reason, the test should represent normal application behavior.
Python Debugging Tools Beyond Execution Time
Performance analysis is stronger when developers combine multiple types of evidence. A function-level profiler may identify expensive code, but it may not explain why a remote request takes longer than expected or why memory consumption increases over several hours.
Logging provides a timeline of application activity. Developers can record timestamps, operation names, request identifiers, response status, and exception details. These records make it easier to compare successful and unsuccessful operations.
For example:
import logging
import time

logging.basicConfig(level=logging.INFO)

def perform_task():
    start = time.perf_counter()

    logging.info("Task started")

    # Application work goes here

    elapsed = time.perf_counter() - start
    logging.info("Task completed in %.3f seconds", elapsed)

perform_task()
This simple pattern records the duration of a task. In production systems, structured logging is often more useful because fields can be searched and grouped automatically.
Developers should avoid logging passwords, authentication tokens, private user data, or other sensitive information. Performance troubleshooting does not justify exposing confidential application data.
Other useful tools include operating-system process monitors, database query analysis, network tracing utilities, and application monitoring platforms. The correct choice depends on where the delay occurs.
Improving Asynchronous Execution Without Creating More Problems
Asynchronous programming can improve application responsiveness when a program spends substantial time waiting for input and output operations. It is particularly useful for workloads involving multiple network requests, database operations, or other compatible asynchronous services.
In synchronous code, one operation may block the current thread while waiting for a response. In asynchronous code, the program can yield control while waiting, allowing other tasks to make progress.
The example uses asyncio.sleep() to simulate an asynchronous wait. The tasks can overlap rather than waiting for each simulated operation to finish one at a time.
This is not a demonstration of an SDK25.5a defect or a real network benchmark. It simply illustrates how asynchronous tasks can cooperate during waiting periods.
Developers should also understand that asynchronous programming does not automatically make CPU-intensive code faster. A long calculation performed directly inside an asynchronous function can still block the event loop and delay other tasks.
For blocking functions that cannot be replaced with asynchronous equivalents, asyncio.to_thread() can move suitable work to a separate thread:
import asyncio
import time

def blocking_operation():
    time.sleep(2)
    return "Operation completed"

async def main():
    result = await asyncio.to_thread(blocking_operation)
    print(result)

asyncio.run(main())
This approach can help keep an event loop responsive when dealing with blocking input/output operations. It is not a universal solution for CPU-heavy work, and developers should understand thread-safety requirements before moving SDK calls into worker threads.
Managing Long-Running Tasks and Resource Usage
An application that runs for only a few seconds may never reveal problems that appear after several hours. Long-running services, scheduled jobs, background workers, and data-processing pipelines need additional attention because small inefficiencies can accumulate.
One common issue is allowing background tasks to grow without limits. If an application creates new tasks faster than it can complete existing ones, the number of pending operations may increase continuously. This can consume memory, increase scheduling overhead, and put pressure on external services.
A semaphore can limit the number of concurrent asynchronous operations:
The semaphore allows no more than five tasks to enter the protected section simultaneously. This is useful when an application needs to control concurrency, although the appropriate limit depends on the service, hardware, and workload.
Resource management also involves closing files, releasing connections, handling exceptions, and avoiding unnecessary object retention. Context managers can help ensure that resources are cleaned up properly.
For example, using a with statement to open a file ensures that the file is closed when the block finishes, including when an exception occurs. Similar patterns are available for many database and network clients.
SDK Compatibility Issues and Dependency Changes
Python applications often depend on multiple packages that evolve independently. An SDK may require a particular range of dependency versions, while another installed package may require a different range. This can create compatibility problems that appear as import failures, runtime exceptions, unexpected behavior, or performance changes.
The first place to check is the project’s dependency configuration. Files such as requirements.txt, pyproject.toml, and lock files help document which package versions the project expects.
Developers should also check the Python version used by the application. A package that works in one interpreter environment may not support another. Native extensions can introduce additional operating-system and architecture requirements.
Updating dependencies can be appropriate when a confirmed issue has been fixed in a newer release. However, upgrading everything without testing is risky. A new version may change function behavior, remove older interfaces, introduce new dependencies, or require code modifications.
Downgrading can also be reasonable when a recent update clearly introduced a reproducible regression. The previous version should be selected based on compatibility and evidence rather than guesswork.
The safest process is to change one relevant component at a time, run automated tests, measure performance, and record the result. This creates a traceable path from the original behavior to the final configuration.
A Practical Troubleshooting Sequence for Python SDK Lag Problems
When a Python application becomes slow, developers benefit from following a consistent investigation rather than immediately reinstalling packages or rewriting code.
Step 1: Record the Exact Symptom
Describe what is happening in measurable terms. Record which operation is slow, how long it takes, whether the issue occurs consistently, and whether the slowdown begins immediately or develops over time.
A vague report such as “the SDK is burning” does not provide enough information for a technical diagnosis. A report stating that a particular API call increased from 200 milliseconds to 2 seconds is much more useful.
Step 2: Confirm the Software Identity
Identify the exact SDK publisher, distribution name, installed version, Python interpreter, and environment. Do not assume that a label such as 25.5a identifies an official Python release.
If the package cannot be identified, pause before applying version-specific fixes. A developer cannot reliably troubleshoot an unknown component.
Step 3: Establish a Baseline
Measure normal application behavior using representative input data. Record execution time, CPU usage, memory consumption, and relevant network or database timings.
A baseline gives developers something meaningful to compare against after a change.
Step 4: Profile the Slow Operation
Use cProfile to locate expensive function calls. Use tracemalloc to investigate Python memory allocations. Add timing logs around network requests, database queries, file operations, and SDK method calls.
The purpose is to isolate the part of the system responsible for the delay.
Step 5: Reproduce the Problem With Fewer Variables
Create a small test that performs the suspected operation without unrelated application features. If the issue disappears, the cause may involve interaction between components rather than the SDK alone.
If the issue remains reproducible in a minimal test, developers have a clearer case for investigating the package itself.
Step 6: Test Dependency Changes Carefully
Compare the current environment with a known working configuration. Change one package or setting at a time and repeat the same test. Keep a record of the results so that successful and unsuccessful changes can be reversed.
Step 7: Monitor the Application After the Fix
A change that improves one test may not solve a long-running problem. Monitor the application under realistic workloads and check whether the improvement remains consistent.
This final stage matters because performance regressions can appear only under sustained traffic, large datasets, or concurrent requests.
When Should Developers Upgrade or Downgrade an SDK?
An SDK update should be considered when there is a specific reason to expect improvement. That reason might be a documented fix from the publisher, a compatibility requirement, a security update, or a reproducible issue addressed by a newer release.
However, developers should not assume that the newest version will always be faster. Performance depends on the application, workload, dependencies, and external services. A newer release may introduce additional processing or change behavior in ways that affect a particular project.
Downgrading makes sense when evidence links a regression to a recent version change and an earlier compatible release restores expected behavior. The older version should not be kept indefinitely without understanding the trade-offs, particularly when security or maintenance updates are involved.
Before making either change, developers should preserve the existing dependency configuration, review compatibility requirements, run tests, and maintain a straightforward rollback option.
For projects with several developers, dependency changes should be documented and shared through the project’s normal version-control process. This reduces the chance of one machine running a different environment from the rest of the team.
The best way to handle recurring slowdowns is to make performance measurement part of normal development rather than waiting for users to report problems.
Applications benefit from automated tests that cover important operations and representative data sizes. Performance tests can track how execution time changes between builds, although results should be interpreted carefully because hardware and system load affect measurements.
Dependency management is equally important. Projects should maintain clear package requirements, use isolated environments, and avoid unplanned changes to production dependencies. Before deployment, developers should test the application with the same major configuration that will be used in production.
Monitoring should cover more than average response time. Averages can hide occasional long delays, so it can be useful to examine slow requests, error rates, memory trends, and resource utilization over time.
Documentation also helps. Recording why a package was selected, which version was tested, and what compatibility requirements exist makes future troubleshooting easier.
The wider history of computing shows how much application performance depends on the relationship between software and the systems supporting it. Even earlier computer workflows relied on coordinated processing and output mechanisms, as illustrated by Pyjamaspapper and its role in older computer printing systems. Modern Python applications are much more flexible, but the basic need to understand how work moves through a system has not disappeared.
Frequently Asked Questions
1. What is Python SDK25.5a burn lag?
Python SDK25.5a burn lag is a search phrase that appears to describe a possible performance slowdown associated with a Python SDK or development environment. Its exact software identity and meaning are not established. Developers should verify the package and measure the reported symptoms before treating it as a specific technical problem.
2. Is SDK25.5a an official Python version?
There is not enough established information to identify SDK25.5a as an official Python language version. Python itself has a defined versioning system, while third-party SDK publishers can use their own naming conventions. The package publisher and installed distribution metadata should be checked to establish what the label represents.
3. Why does Python code become slow?
Python code can become slow because of inefficient algorithms, excessive data processing, memory pressure, blocking operations, slow external services, or dependency problems. The cause depends on the workload. Profiling and timing individual operations are more reliable than guessing based on the programming language alone.
4. Can high CPU usage cause application lag?
Yes. When a process uses substantial CPU time, other work may have to wait for processor resources. This can make an application less responsive, particularly when several demanding operations run simultaneously. However, high CPU usage is not the only cause of lag; network delays, storage operations, and memory pressure can produce similar symptoms.
5. How can developers identify Python memory leaks?
Developers can compare memory usage over time and inspect allocations with tools such as tracemalloc. Repeated snapshots can help identify code locations associated with growing allocations. A rising memory graph alone does not prove a leak, because caching and intentional object retention can also increase memory consumption.
6. Which tools help diagnose Python performance problems?
Useful tools include cProfile for function-level profiling, tracemalloc for Python memory allocations, time.perf_counter() for timing operations, and logging for recording application activity. Operating-system monitoring and database or network diagnostics can help investigate problems outside Python code.
7. Should developers downgrade a problematic SDK?
Downgrading can be reasonable when a reproducible performance regression appears after a specific update and an earlier compatible version restores expected behavior. Developers should test the change in an isolated environment, check compatibility, preserve dependency records, and consider any security or maintenance implications.
8. How can asynchronous programming improve performance?
Asynchronous programming can improve responsiveness when applications spend substantial time waiting for network, database, or other input/output operations. It allows other tasks to progress while one operation waits. It does not automatically accelerate CPU-intensive calculations, and blocking functions can still prevent an event loop from responding.
9. How do you determine whether an SDK is responsible for slow execution?
Identify the exact SDK version, measure the affected operation, and compare the result with a minimal test or a known working dependency configuration. Examine CPU, memory, network, and database activity as well. If the slowdown can be consistently reproduced with the SDK under controlled conditions, the evidence becomes stronger, although the underlying cause may still involve configuration or external services.
Conclusion
The phrase python sdk25.5a burn lag should not be treated as proof of an official Python error or a confirmed defect in a specific SDK release. Its exact identity remains uncertain, and the label alone does not provide enough information to justify a version-specific fix.
What developers can investigate are the symptoms behind the phrase: slow execution, rising CPU usage, increasing memory consumption, blocked operations, network delays, and dependency compatibility problems. Tools such as cProfile, tracemalloc, time.perf_counter(), and structured logging help turn vague performance complaints into measurable evidence.
The most reliable troubleshooting process begins by identifying the actual package, establishing a performance baseline, profiling the affected operation, and comparing controlled dependency configurations. Updating or downgrading should follow evidence rather than guesswork.
Ultimately, good Python performance optimization is not about applying a supposed fix to an unfamiliar version label. It is about understanding where time and resources are being spent, reproducing the problem, and changing the smallest relevant part of the system. That approach is more dependable, easier to maintain, and far more useful than assuming every slowdown has the same cause.